Training, history and memory describe different uses
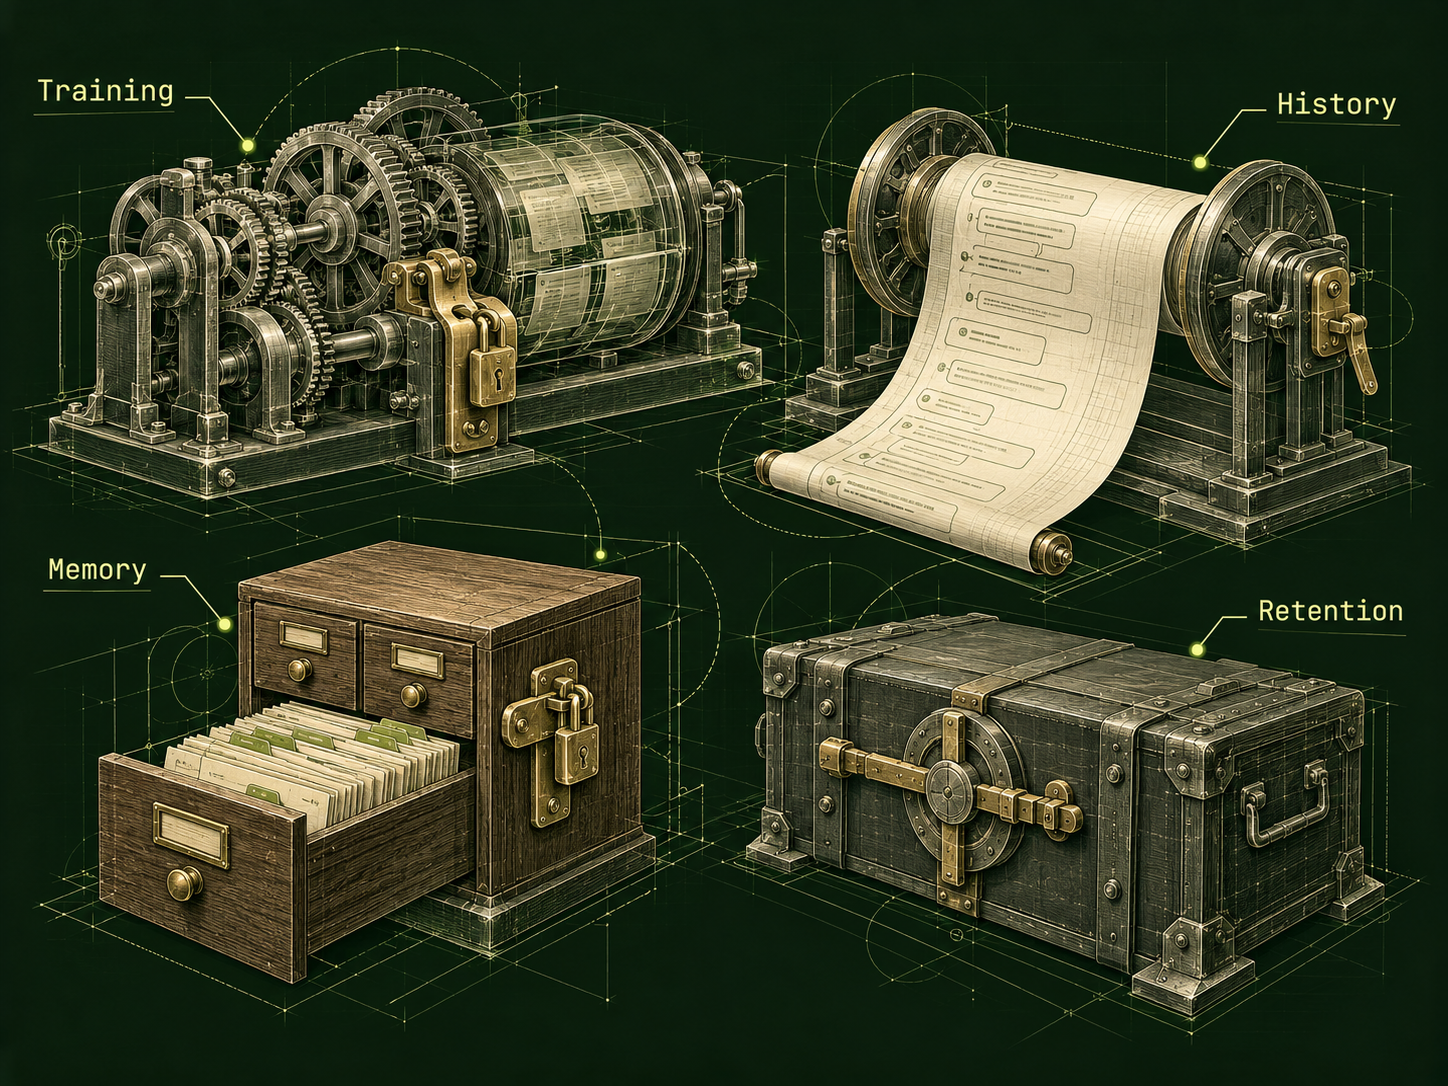
Training or model improvement concerns using eligible content to develop model behavior. Chat history concerns keeping conversations available to the account. Memory or personalization concerns information reused to tailor later interactions. Retention concerns how long records remain for the purposes described by the service.
These uses can overlap without being identical. A conversation may remain visible in history while being excluded from training. Removing something from the interface does not by itself describe every backend retention process.
Ask about each use separately. A policy sentence saying “not used for training” answers one question. It does not automatically establish where processing happens, who can access logs or whether a connected third-party tool receives part of the request. Those questions require their own documentation.
What ChatGPT’s training control actually describes
OpenAI’s current help documentation says eligible content from individual services may be used to improve models, with controls to opt out. It distinguishes that arrangement from business offerings, where inputs and outputs are not used for training by default. Check the specific service rather than extending one rule across every account.
Its documentation describes turning off “Improve the model for everyone” to exclude new conversations from training. That is a model-improvement control. It is not a statement that the conversation ceases to be processed or that every existing record is erased.
The same document describes a feedback exception: if you choose to provide feedback, the associated conversation may be used even after opting out. Read the complete policy for the action you are taking. These are documented OpenAI examples checked for this guide, not claims about DarkGPT’s data handling.
Ask the service five concrete data questions
| Question | Look for | Avoid assuming |
|---|---|---|
| Who processes the request? | Named provider and connected services. | The website name is the only processor. |
| Is content used for model improvement? | Account-specific default and opt-out scope. | All products share the consumer default. |
| What remains in history or memory? | Separate controls and deletion instructions. | A training opt-out disables personalization. |
| What records are retained? | Retention purposes and applicable exceptions. | An empty sidebar means no records remain. |
| What happens through external tools? | Tool-specific data disclosures. | The chatbot’s policy covers every destination. |
Save the policy link and the date of your review. Settings and account arrangements can change. If the policy does not resolve an important requirement, treat it as an open question rather than filling the gap with the broadest privacy-friendly interpretation.
A training opt-out does not make every upload suitable
Imagine an original workplace scenario: you want help improving a support response. The ticket contains a customer’s name, account identifier and a pasted access token. Even if model training is disabled, uploading the raw ticket still involves processing those details.
Replace the customer with an invented identifier, remove the token and preserve only the information needed to revise the response. Keep the meaning of the issue without sending an unnecessary record. Do not ask the chatbot to remove secrets only after you have already uploaded them.
For material governed by a workplace rule, use the approved environment and follow the applicable handling requirements. A personal account setting does not establish authorization to share organizational records. The useful first step is reducing the data and confirming the permitted workflow.
Keep the conclusion as narrow as the evidence
A careful conclusion might be: “This account’s new conversations are excluded from model improvement under the documented setting; history and retention are governed separately.” That is more useful than saying the service never uses your data.
If your requirement is no remote processing, a hosted training opt-out is not the same arrangement. Evaluate a genuinely local workflow and inspect its dependencies. If your requirement concerns retention, look for the policy and control that address retention directly.
For DarkGPT, review the published privacy policy and verify any handling requirement against the actual service configuration. This guide explains the questions to ask. It does not invent a deletion promise or assume that a third-party setting controls the entire application.
Sources & further reading
Follow the original source to check its date and scope.
- How your data is used to improve model performance
OpenAI | service-specific training defaults, opt-out controls and the feedback exception.
Make it your next question
Try this prompt
Use this promptHelp me read an AI service’s data policy that I provide. Separate model training from history, memory and retention. Identify what each setting changes and what the document does not establish. Do not assume one provider’s rules apply to another.
Opens chat with this prompt filled in. You choose when to send it.